
The Skin Tone Blind Spot: Why Imported Skin Analysis AI Misreads Latin American Skin
Most skin analysis AI was trained on datasets that underrepresent Latin American skin tones and undertones. Here's why that matters for conversion, returns, and trust — and what to ask vendors before you buy.
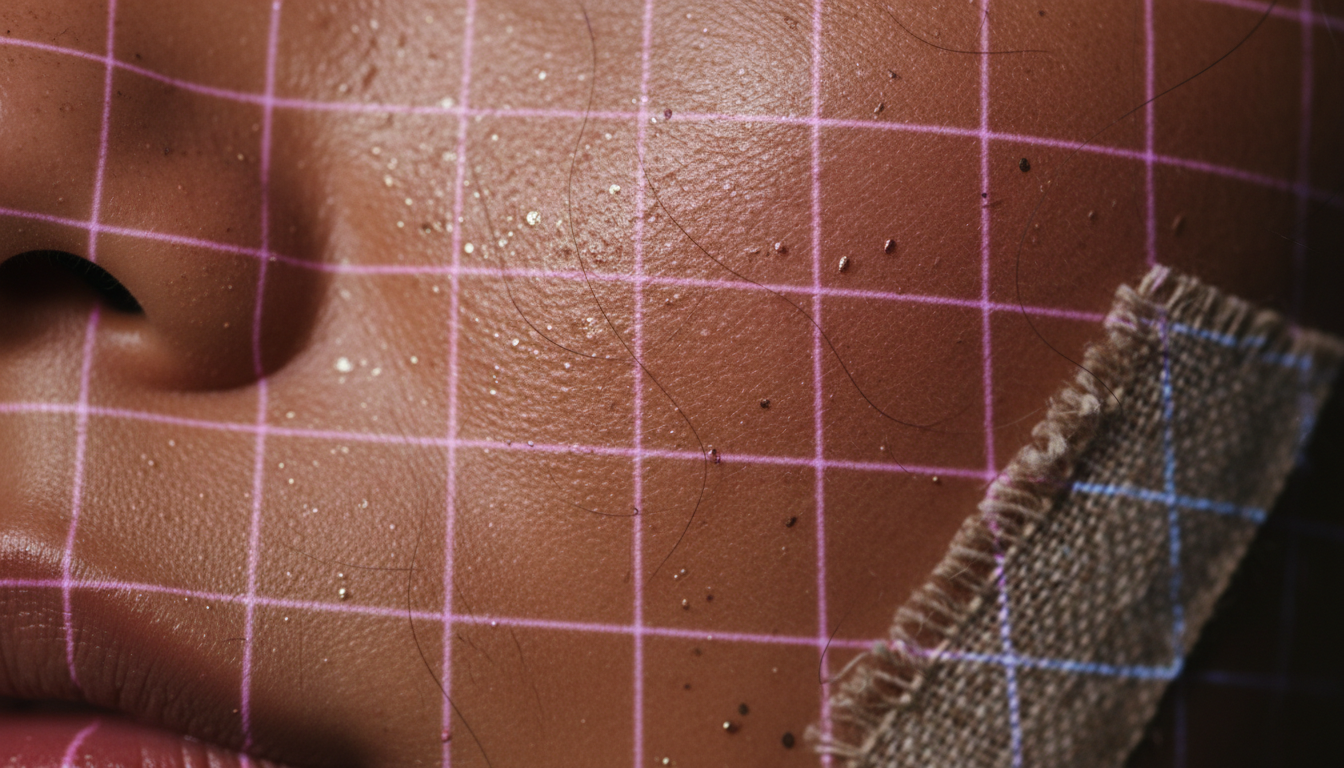
The New Diagnostic Layer in Beauty E-commerce
AI-powered skin analysis has quietly become table stakes on beauty e-commerce sites and apps: upload a selfie, get an instant read on oiliness, pore visibility, dark spots, or undertone, and walk away with a personalized product shortlist. For brands, it's a conversion and retention tool. For shoppers, it feels like expert advice without the wait for an expert.
But there's a structural question most decision-makers never ask before signing a vendor contract: what faces was the model actually trained on?
Where Global Models Break Down
Most skin analysis engines sold internationally were built on datasets assembled in North America, Europe, or East Asia. For Latin American markets, that creates three concrete problems.
Training Data Imbalance
Computer vision research has repeatedly shown that facial analysis models perform worse on underrepresented skin tones simply because they saw fewer examples during training. When a dataset skews toward lighter Fitzpatrick types, accuracy quietly degrades as melanin density increases or undertone shifts.
Lighting and Camera Bias
Selfie-based analysis is only as good as the white balance and exposure assumptions baked into the model. Tropical daylight, warm indoor lighting, and the phone cameras common across Brazil and Latin America behave differently than the studio-calibrated images many global models learned from. The result: oiliness and redness misread, dark spots over- or under-detected.
Undertone Complexity
Brazil, in particular, has one of the most mixed populations on earth. Undertone — warm, cool, neutral, olive — doesn't map neatly onto skin tone depth, and models trained on more homogeneous populations tend to collapse this nuance into broad, inaccurate buckets. Concerns like hyperpigmentation and uneven tone, which are especially common across deeper and mixed skin tones, get flattened into one-size-fits-all recommendations.
Why This Isn't a Minor Bug
A tool that misreads skin tone doesn't just produce a slightly-off suggestion — it undermines the entire value proposition of personalization. For a brand investing in an AI advisor specifically to build trust and lift conversion, an inaccurate read for a meaningful share of visitors directly hits:
- Conversion rate, when recommended products don't match actual skin needs
- Return and complaint rates, when purchases based on bad advice underdeliver
- Brand trust, which is far harder to rebuild than to build
In a region where mixed and deep skin tones are the majority of the shopper base, not an edge case, this is a core accuracy problem — not a patch for later.
How MaIA Was Built Differently
B4A's MaIA was trained from day one on a proprietary base of hundreds of thousands of selfies from Brazilian consumers, spanning the full range of skin tones and undertones actually shopping in the market — not a global average retrofitted with a handful of local examples.
Just as important is what happens after the analysis runs: MaIA's recommendations connect to a closed loop of real purchase and review data from B4A's own consumer ecosystem, including the glam subscription base. The model isn't only validated against labeled images — it's continuously checked against whether the products it recommended actually performed well for the skin tones they were recommended to, and refined from there.
A Vendor Vetting Checklist
Before selecting — or renewing — an AI skin advisor, ask vendors directly:
- What is the geographic and demographic composition of the training dataset?
- How does accuracy vary across skin tone and undertone, and can they share that breakdown?
- Was the model calibrated for local lighting conditions and device types, or only studio-standard imagery?
- Is there a feedback loop connecting analysis output to real purchase and satisfaction data, or does it run static post-deployment?
- Who is accountable for retraining as the underlying consumer base evolves?
Vendors who can't answer these clearly are likely selling a global average dressed up as personalization.
The Takeaway
For beauty brands expanding into Brazil and Latin America, an AI beauty advisor is only as useful as the data it was built on. A model trained on the wrong faces will consistently under-deliver for the majority of shoppers in this region, no matter how polished the interface looks. Before investing in — or expanding — a skin analysis tool here, ask where its intelligence actually comes from.
B4A Serviços de Tecnologia e Comércio S.A.
Avenida Jornalista Roberto Marinho, nº 85, 11º Andar (Conjunto 112), Cidade Monções - CEP 04576-010 - Cidade de São Paulo, Estado de São Paulo