
Skin Analysis AI Was Trained on the Wrong Faces: Why Brazilian Skin Data Matters
Most skin analysis AI was built on datasets that don't reflect Brazil's population. Here's why that gap matters for accuracy, trust, and conversion — and how a LATAM-first dataset changes the equation.
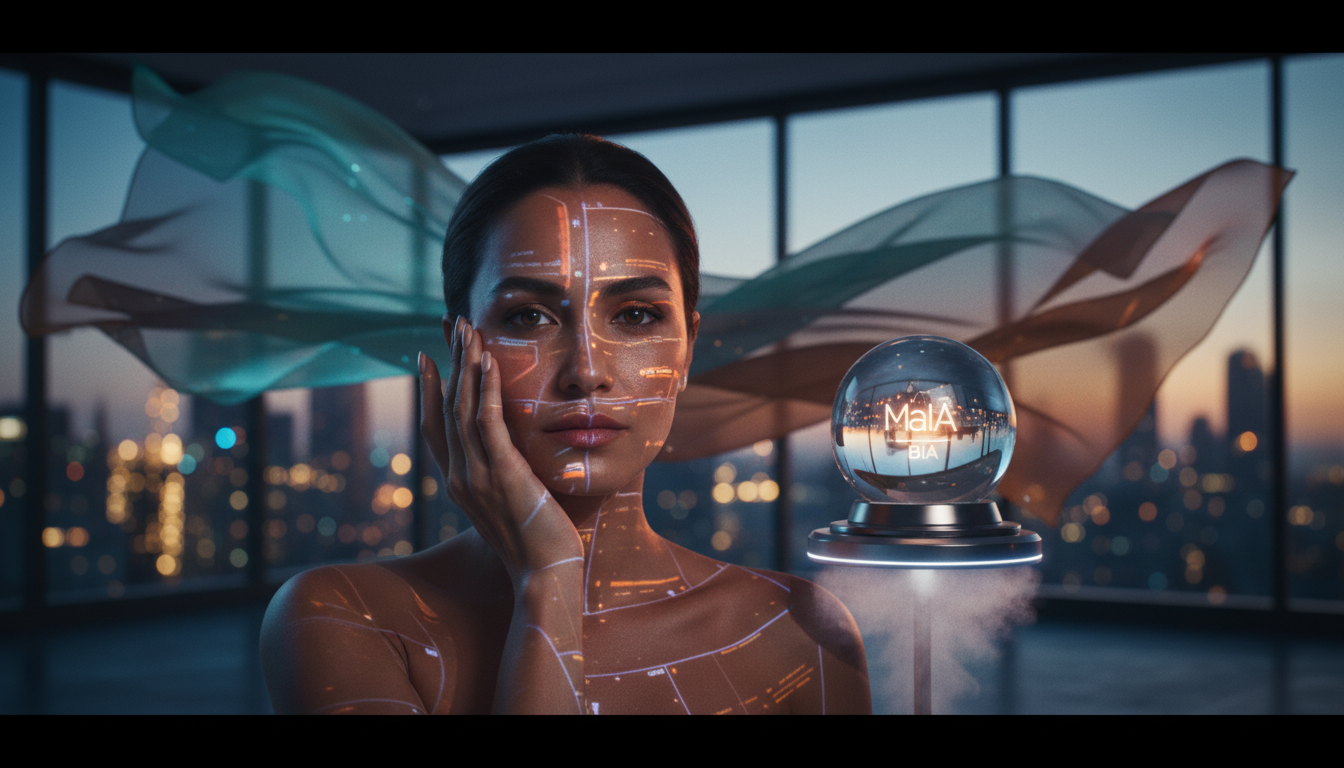
The Blind Spot in Beauty AI
Skin analysis has become the front door of digital beauty — the selfie-in, recommendation-out moment that promises personalization at scale. But few brands ask a basic question before licensing a vendor: whose faces trained this model?
For most global skin analysis tools, the honest answer is a narrow one. Training sets skew toward the markets where the vendor's engineering team and early clients are based — often East Asia, North America, or Western Europe. Brazil, with one of the most phenotypically diverse populations on earth, rarely shows up in meaningful volume.
That gap doesn't show up as a rounding error. It shows up as visibly wrong skin tone readings, miscategorized concerns, and recommendations that erode trust exactly at the moment a brand is trying to build it.
Why "Global" Training Data Doesn't Mean Representative
The Fitzpatrick Problem
Most computer vision models for skin are still validated against the Fitzpatrick scale, a classification built for dermatology research, not machine learning at consumer scale. Brazil's population sits across the full range of that scale — often within a single family, not just across the country. A model that under-samples the middle and darker points of that spectrum will systematically misjudge a meaningful share of any Brazilian user base.
Undertones, Not Just Tones
Tone is only half the picture. Undertone — warm, cool, neutral — drives real product-matching decisions in foundation, concealer, and color cosmetics. Datasets built on populations with less undertone variance haven't seen enough examples to generalize well to Brazilian skin, where undertone diversity is the norm, not the exception.
Hyperpigmentation Looks Different Across Populations
Concerns like uneven tone and texture present differently depending on baseline skin tone and sun exposure — and Brazil's UV environment is intense year-round. A model trained mostly on lower-melanin, lower-UV-exposure populations will consistently misread these patterns, generating cosmetic recommendations that miss the actual concern.
What This Costs a Brand in Brazil
For a brand entering or scaling in Brazil, a poorly calibrated skin analysis tool isn't a technical footnote — it's a business risk:
- Recommendation mismatch that pushes the wrong SKU, hurting conversion and increasing returns.
- Visible tone/undertone errors that consumers notice immediately and share publicly.
- Erosion of trust in the one interaction meant to build it — right at the top of the funnel.
- Wasted marketing spend driving traffic into an experience that doesn't convert on arrival.
In a market where word of mouth moves fast, a bad AI advisor experience can undercut an otherwise strong launch.
Built on Brazilian Faces, From the Start
This is the core design decision behind MaIA, B4A's white-label conversational AI beauty advisor: it was trained from the outset on a proprietary base of hundreds of thousands of selfies from Brazilian consumers, paired with real purchase and review data through B4A's closed-loop ecosystem — not retrofitted for the market after launching elsewhere.
That distinction matters more than it sounds. A model trained for Brazil sees the full range of tones and undertones as the default distribution, not an edge case to patch later. And because MaIA's recommendations connect back to actual purchase and repurchase behavior via BIA, B4A's beauty intelligence layer, brands get a feedback loop that keeps improving — not a static model shipped once and left alone.
(For clarity: skin analysis in this context supports cosmetic product matching and personalization — it is not a diagnostic or medical tool.)
What to Ask Before You License a Skin Analysis AI
Before signing with any vendor, beauty brands entering or scaling in Brazil should ask:
- What population was the training data sourced from, and in what proportions?
- How is accuracy validated across the tone and undertone spectrum — not just on average?
- Does the model improve from local usage data, or ship as a fixed asset?
- Is there a feedback loop connecting analysis to actual purchase and repeat behavior?
- Who owns the resulting first-party data — the vendor, or the brand?
Vendors who can't answer the first question specifically are likely working from a dataset that wasn't built with Brazil in mind.
The Takeaway
Personalization is only as good as the data behind it. For any brand treating skin analysis AI as a serious conversion and trust tool in Brazil — not a novelty widget — the training population is a due-diligence question, not a footnote. Ask it before you buy, not after your consumers notice the answer for you.
B4A Serviços de Tecnologia e Comércio S.A.
Avenida Jornalista Roberto Marinho, nº 85, 11º Andar (Conjunto 112), Cidade Monções - CEP 04576-010 - Cidade de São Paulo, Estado de São Paulo